DevGraph — Repository Discovery & Issue Indexing Platform
Repository discovery built around a connected user–repository–issue graph. Independent feed snapshots and local search state keep discovery responsive without refetching on every keystroke.
Problem & context
Make personal and suggested repositories navigable, with repository documents linked to owners and issues.
My contribution
repository discovery and search UI, Express repository handlers, and MongoDB owner/issue relationships.
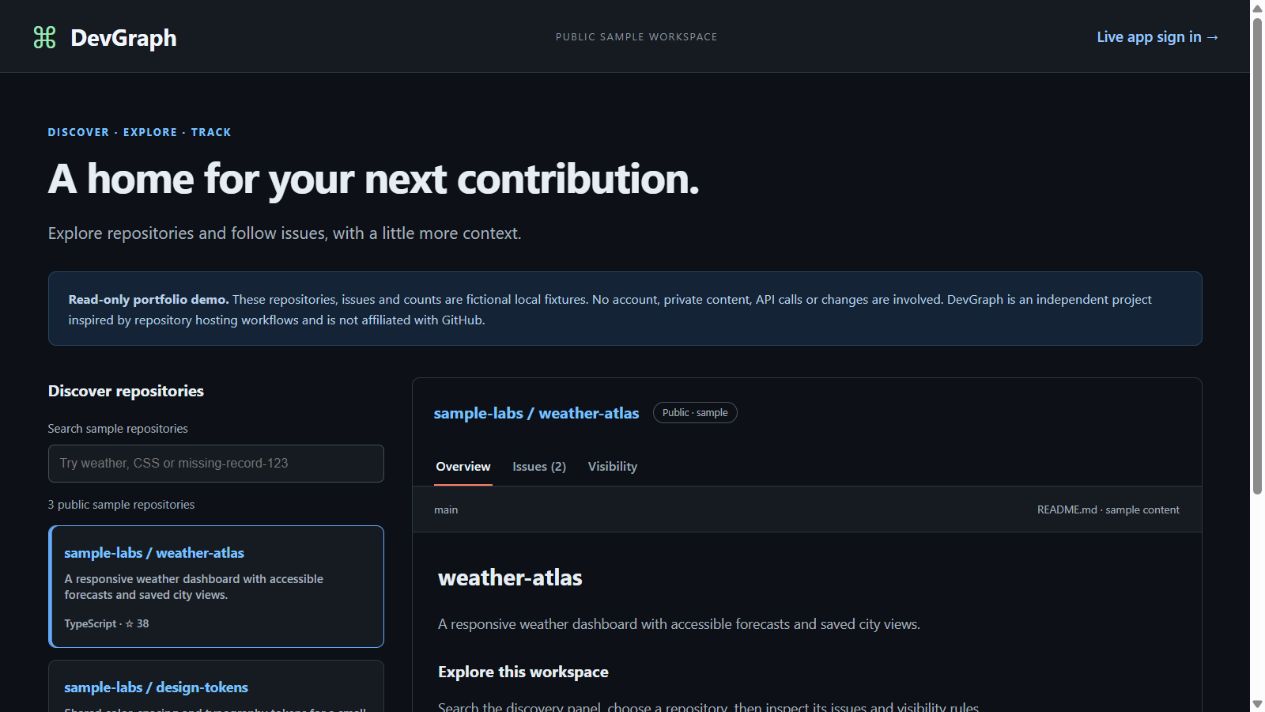
Inspect the workflow.
Explore the sample workflow without creating an account. The application renders bundled fixtures through its public preview interface.
Open sample workspaceRead-only fixtures · no sign-in · no real generation or financial action
Failure path: A create request omits the repository name or supplies a malformed owner identifier.
The create handler returns 400 before constructing and saving a repository. Other caught repository errors return a server-error response; database recovery was not executed in this source review.
Authenticated app ↗An engineering decision.
filtering the existing array avoids a search request on each keystroke. The tradeoff is that results cover the loaded personal feed and can become stale until reloaded.
Implemented approach
Load personal and suggested repository feeds independently and filter the loaded personal feed by name in client state.
Alternative & tradeoff
Send a repository search request for every change to the search field.
Follow the system.
Verified behavior & limitations.
What the evidence establishes
- Source review: the dashboard maintains separate personal repositories, suggestions, search query, and filtered-result state.
- Source review: a query/state effect filters personal repository names with a case-insensitive substring match.
- Source review: repository creation rejects missing names and malformed owner ObjectIds before saving.
- Source review: repository reads populate owner and issue document references; a separate query lists records by owner.
Boundaries & remaining work
- Client-side feed reuse is not a shared cache, a benchmark, or proof of large-dataset scalability.
- The reviewed dashboard snapshot uses localhost API URLs. A public URL alone does not verify a working deployed repository journey.
- A visibility field and valid owner identifier do not establish complete privacy enforcement or authorization. Live database and multi-user access paths were not exercised for this case study.
Inspect the source.
References are pinned to the reviewed revision. Public sample screens demonstrate the interface with fixtures; source review and executed checks are labelled separately.