RAG Book Assistant — Document Q&A
A deployed Python application that turns selectable PDF text into source-grounded answers. OpenAI embeddings and diversity-aware retrieval find relevant passages, GPT-4o-mini answers from that context, and expandable page excerpts let visitors inspect the evidence.
The problem
A deployed Python application that turns selectable PDF text into source-grounded answers. OpenAI embeddings and diversity-aware retrieval find relevant passages, GPT-4o-mini answers from that context, and expandable page excerpts let visitors inspect the evidence.
My contribution
Built PDF extraction, overlapping chunking, OpenAI embeddings, MMR retrieval, and structured answer validation; connected them to a session-isolated Streamlit interface and deployed the app with server-side secrets.
Product features
- PDF upload with selectable-text extraction and page references
- Overlapping document chunks with preserved page numbers
- OpenAI embeddings with cosine similarity and maximal marginal relevance retrieval
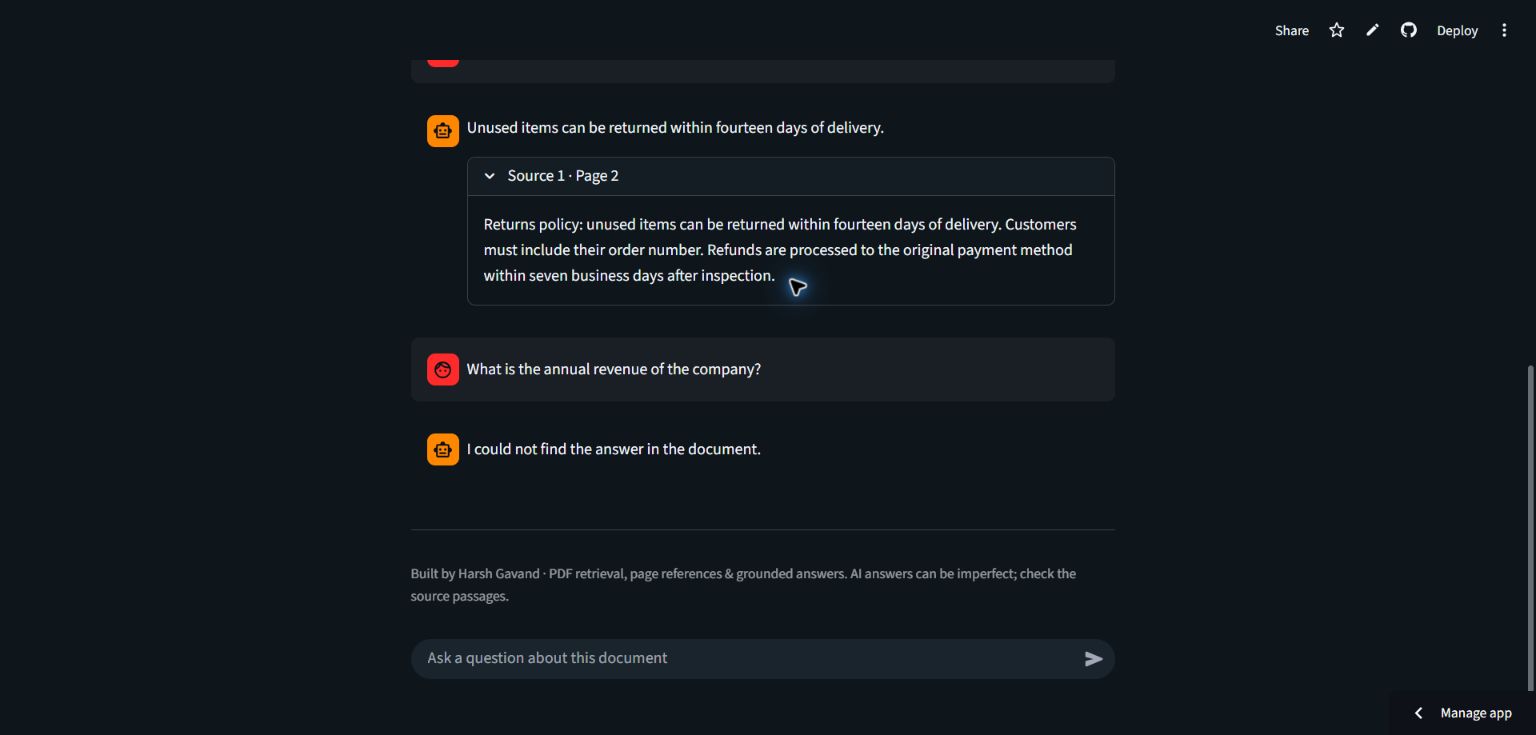
- GPT-4o-mini answers with validated source IDs and expandable page excerpts
- Context-aware responses when the document does not contain an answer
- Session-isolated document indexes, clear-document controls, and request admission limits
Engineering work
- Source-grounded retrieval: Embed overlapping PDF passages, select up to four results with cosine similarity and maximal marginal relevance, and validate the source IDs returned with GPT-4o-mini answers.
- Visitor isolation: Keep document vectors and conversations in Streamlit session state, with clear-document controls and no shared persistent index.
- Bounded API workflow: Validate PDF size, page count, text length, questions, and generated citations; apply session and process-level usage caps before paid requests.
Outcome
Turns PDF content into a searchable conversation with supporting page excerpts, helping readers locate answers and inspect the original source without scanning the full document.